Case study · Software
Three Apps in Raw PHP: A Lesson in SQL Transactions
A café, a library, and a gym - three management systems built in plain PHP and MySQL with no framework, where the real lessons were all about transactions.
Key takeaways
- Three management systems built in plain PHP 8.2 and MySQL, no framework and no ORM, so the database work stays in the open.
- The recurring lesson across all three was the transaction: multi-table writes that must either all land or all roll back.
- Derived numbers like stock, seats, and fines are computed from the source rows, never cached as a counter that can drift.
- stack
- PHP 8.2 · MySQL
Skills
- Relational data modelling
- recipe/ingredient links, holds queues, and capacity-bounded bookings expressed directly in schema.
- SQL transactions & integrity
- multi-table all-or-nothing writes, derived aggregates over cached counters, and concurrency-aware booking logic.
- Plain PHP + PDO
- role-based access, the built-in PHP server for local dev, and Docker Compose with automatic seeding.
The write-up · 5 sections · 4 min read
Why no framework?
It’s tempting to reach for Laravel and let an ORM hide the database. I deliberately didn’t. These three systems, a café back-office, a library, and a gym, are built in plain PHP 8.2 and MySQL, no framework and no ORM, precisely so the database work couldn’t be hidden. Each one runs on the built-in PHP server against hand-written SQL. And in all three, the part that actually taught me something was the same: multi-step writes that have to be all-or-nothing.
BrewQuery
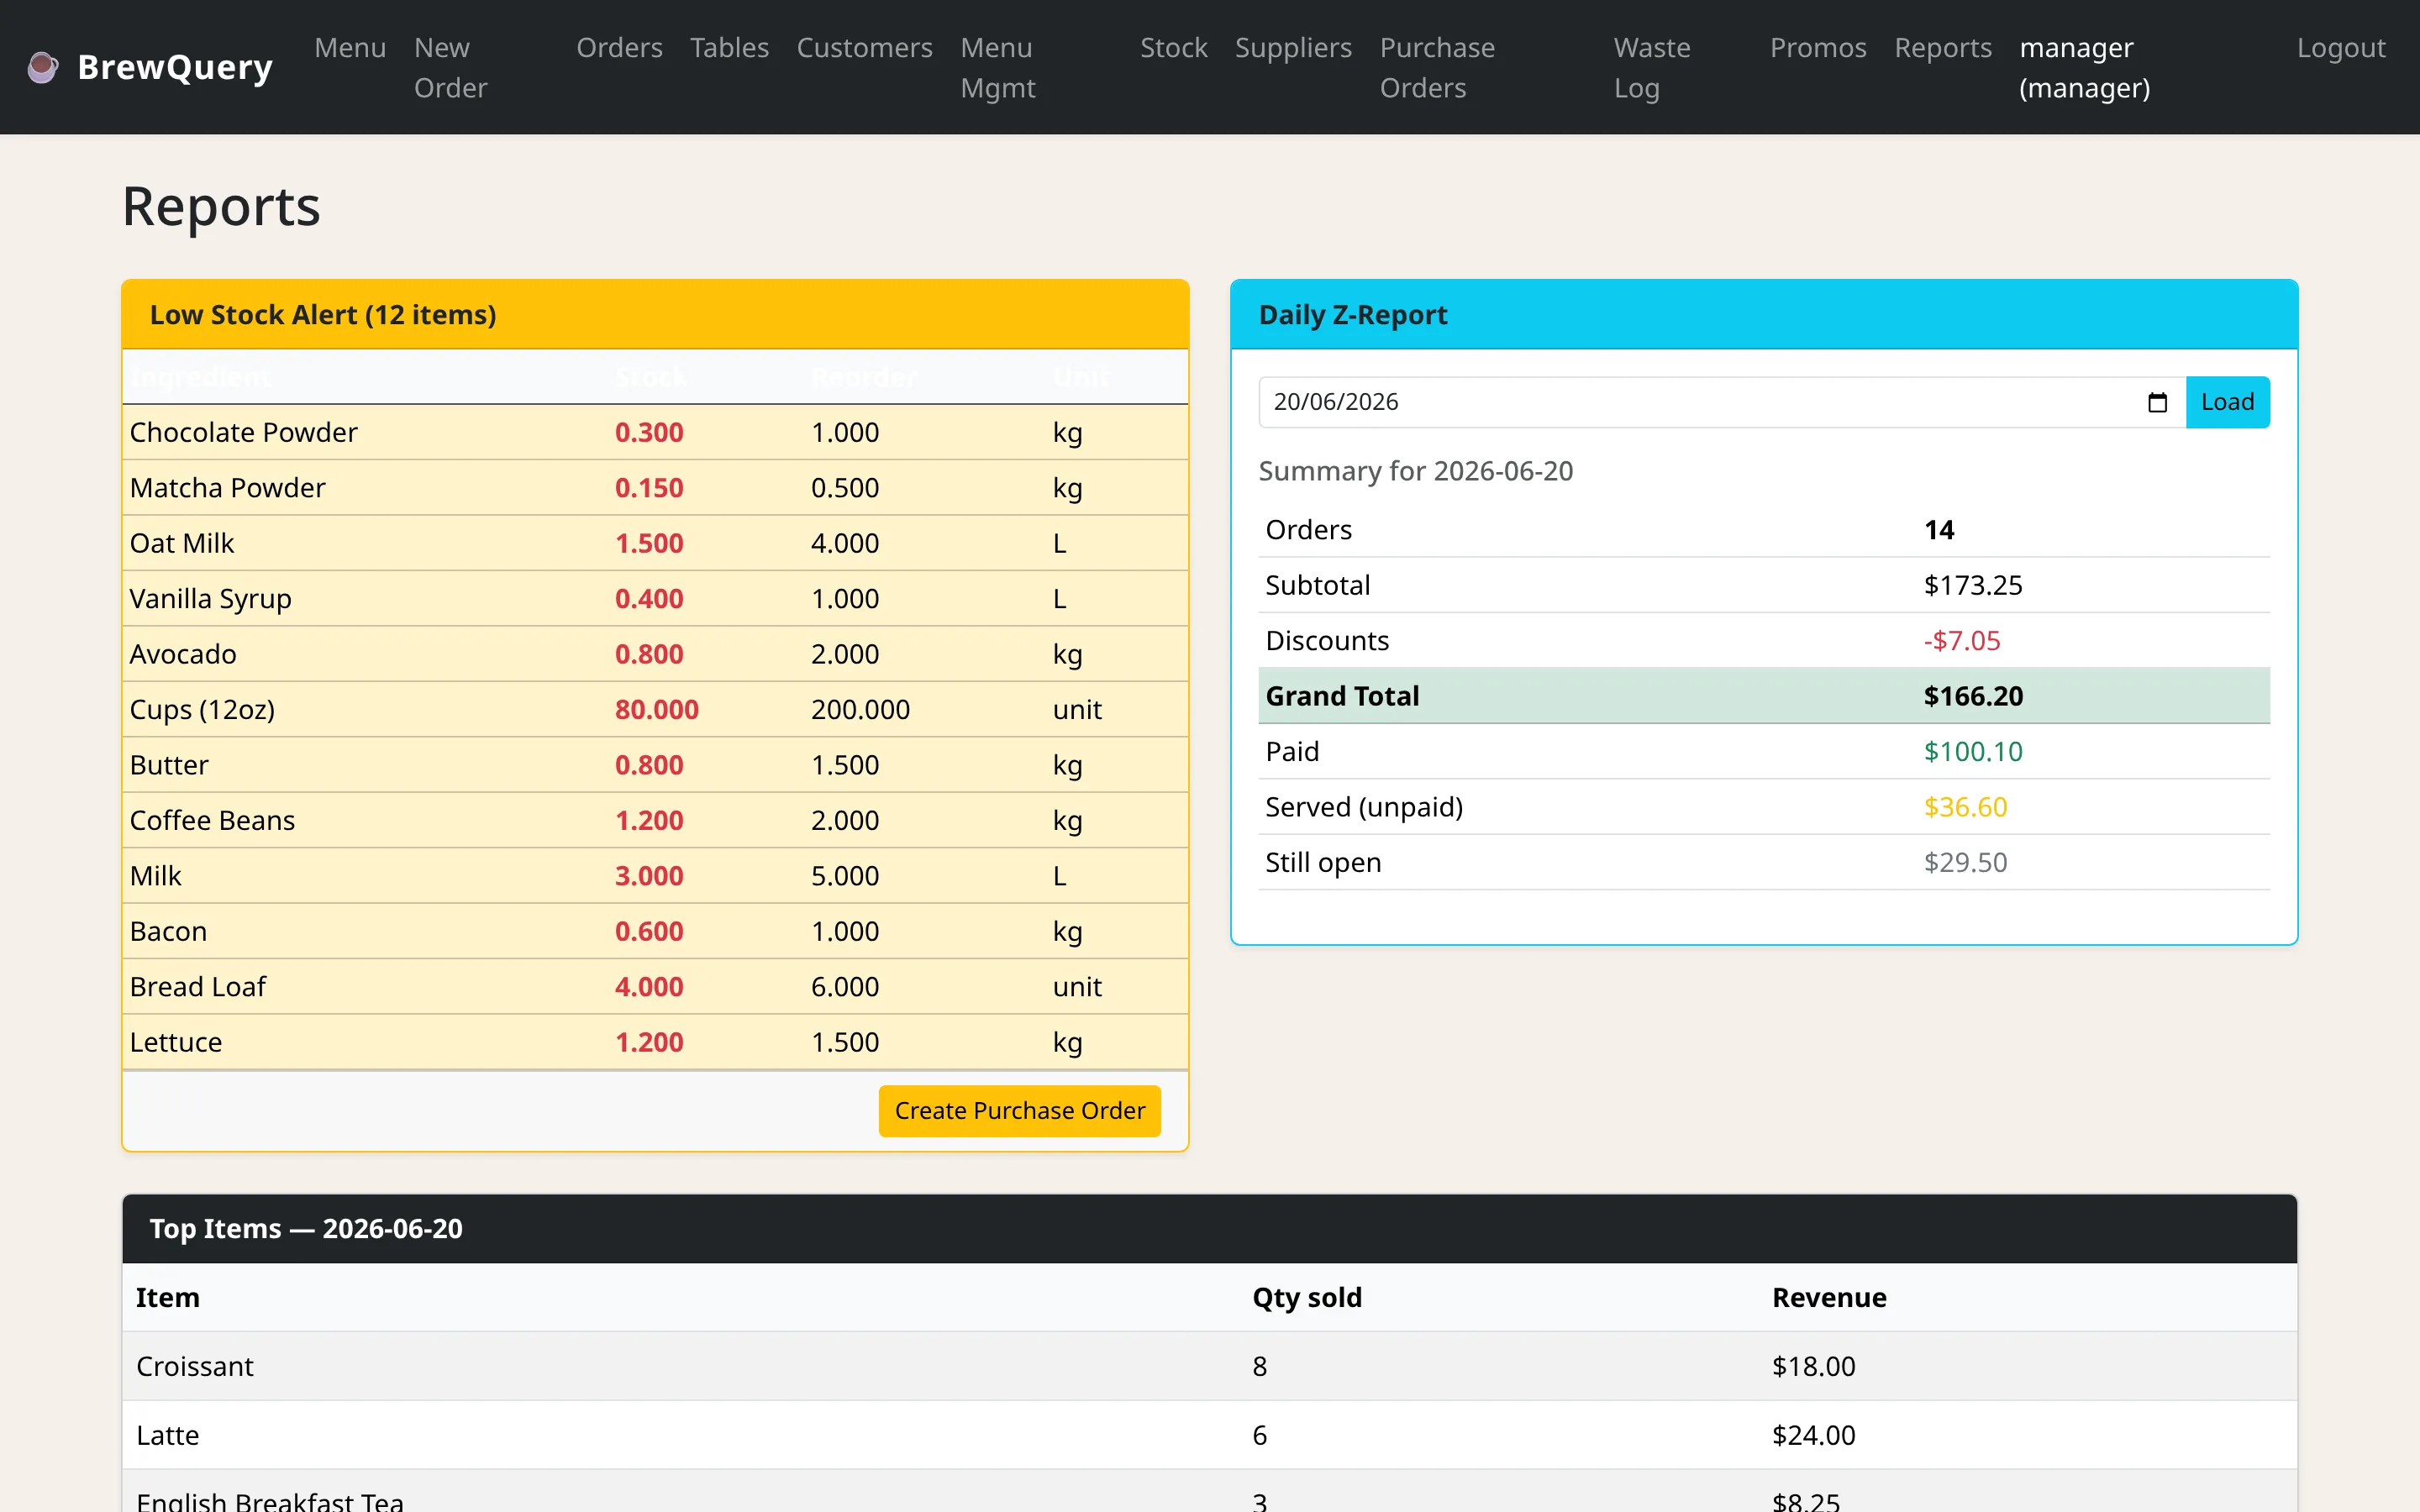
BrewQuery takes orders, tracks ingredient stock, and raises purchase orders when things run low. The menu links to ingredients through a recipe table, so submitting an order deducts stock across several ingredients in one transaction, and receiving a supplier PO bumps it all back up the same way. Get the transaction boundary wrong and you sell a coffee whose milk was never debited.
There are two roles with genuinely different surfaces: a cashier who builds orders, marks them served/paid, and checks loyalty points; and a manager who owns menu CRUD, stock, suppliers, purchase orders, and reports.
ShelfAware
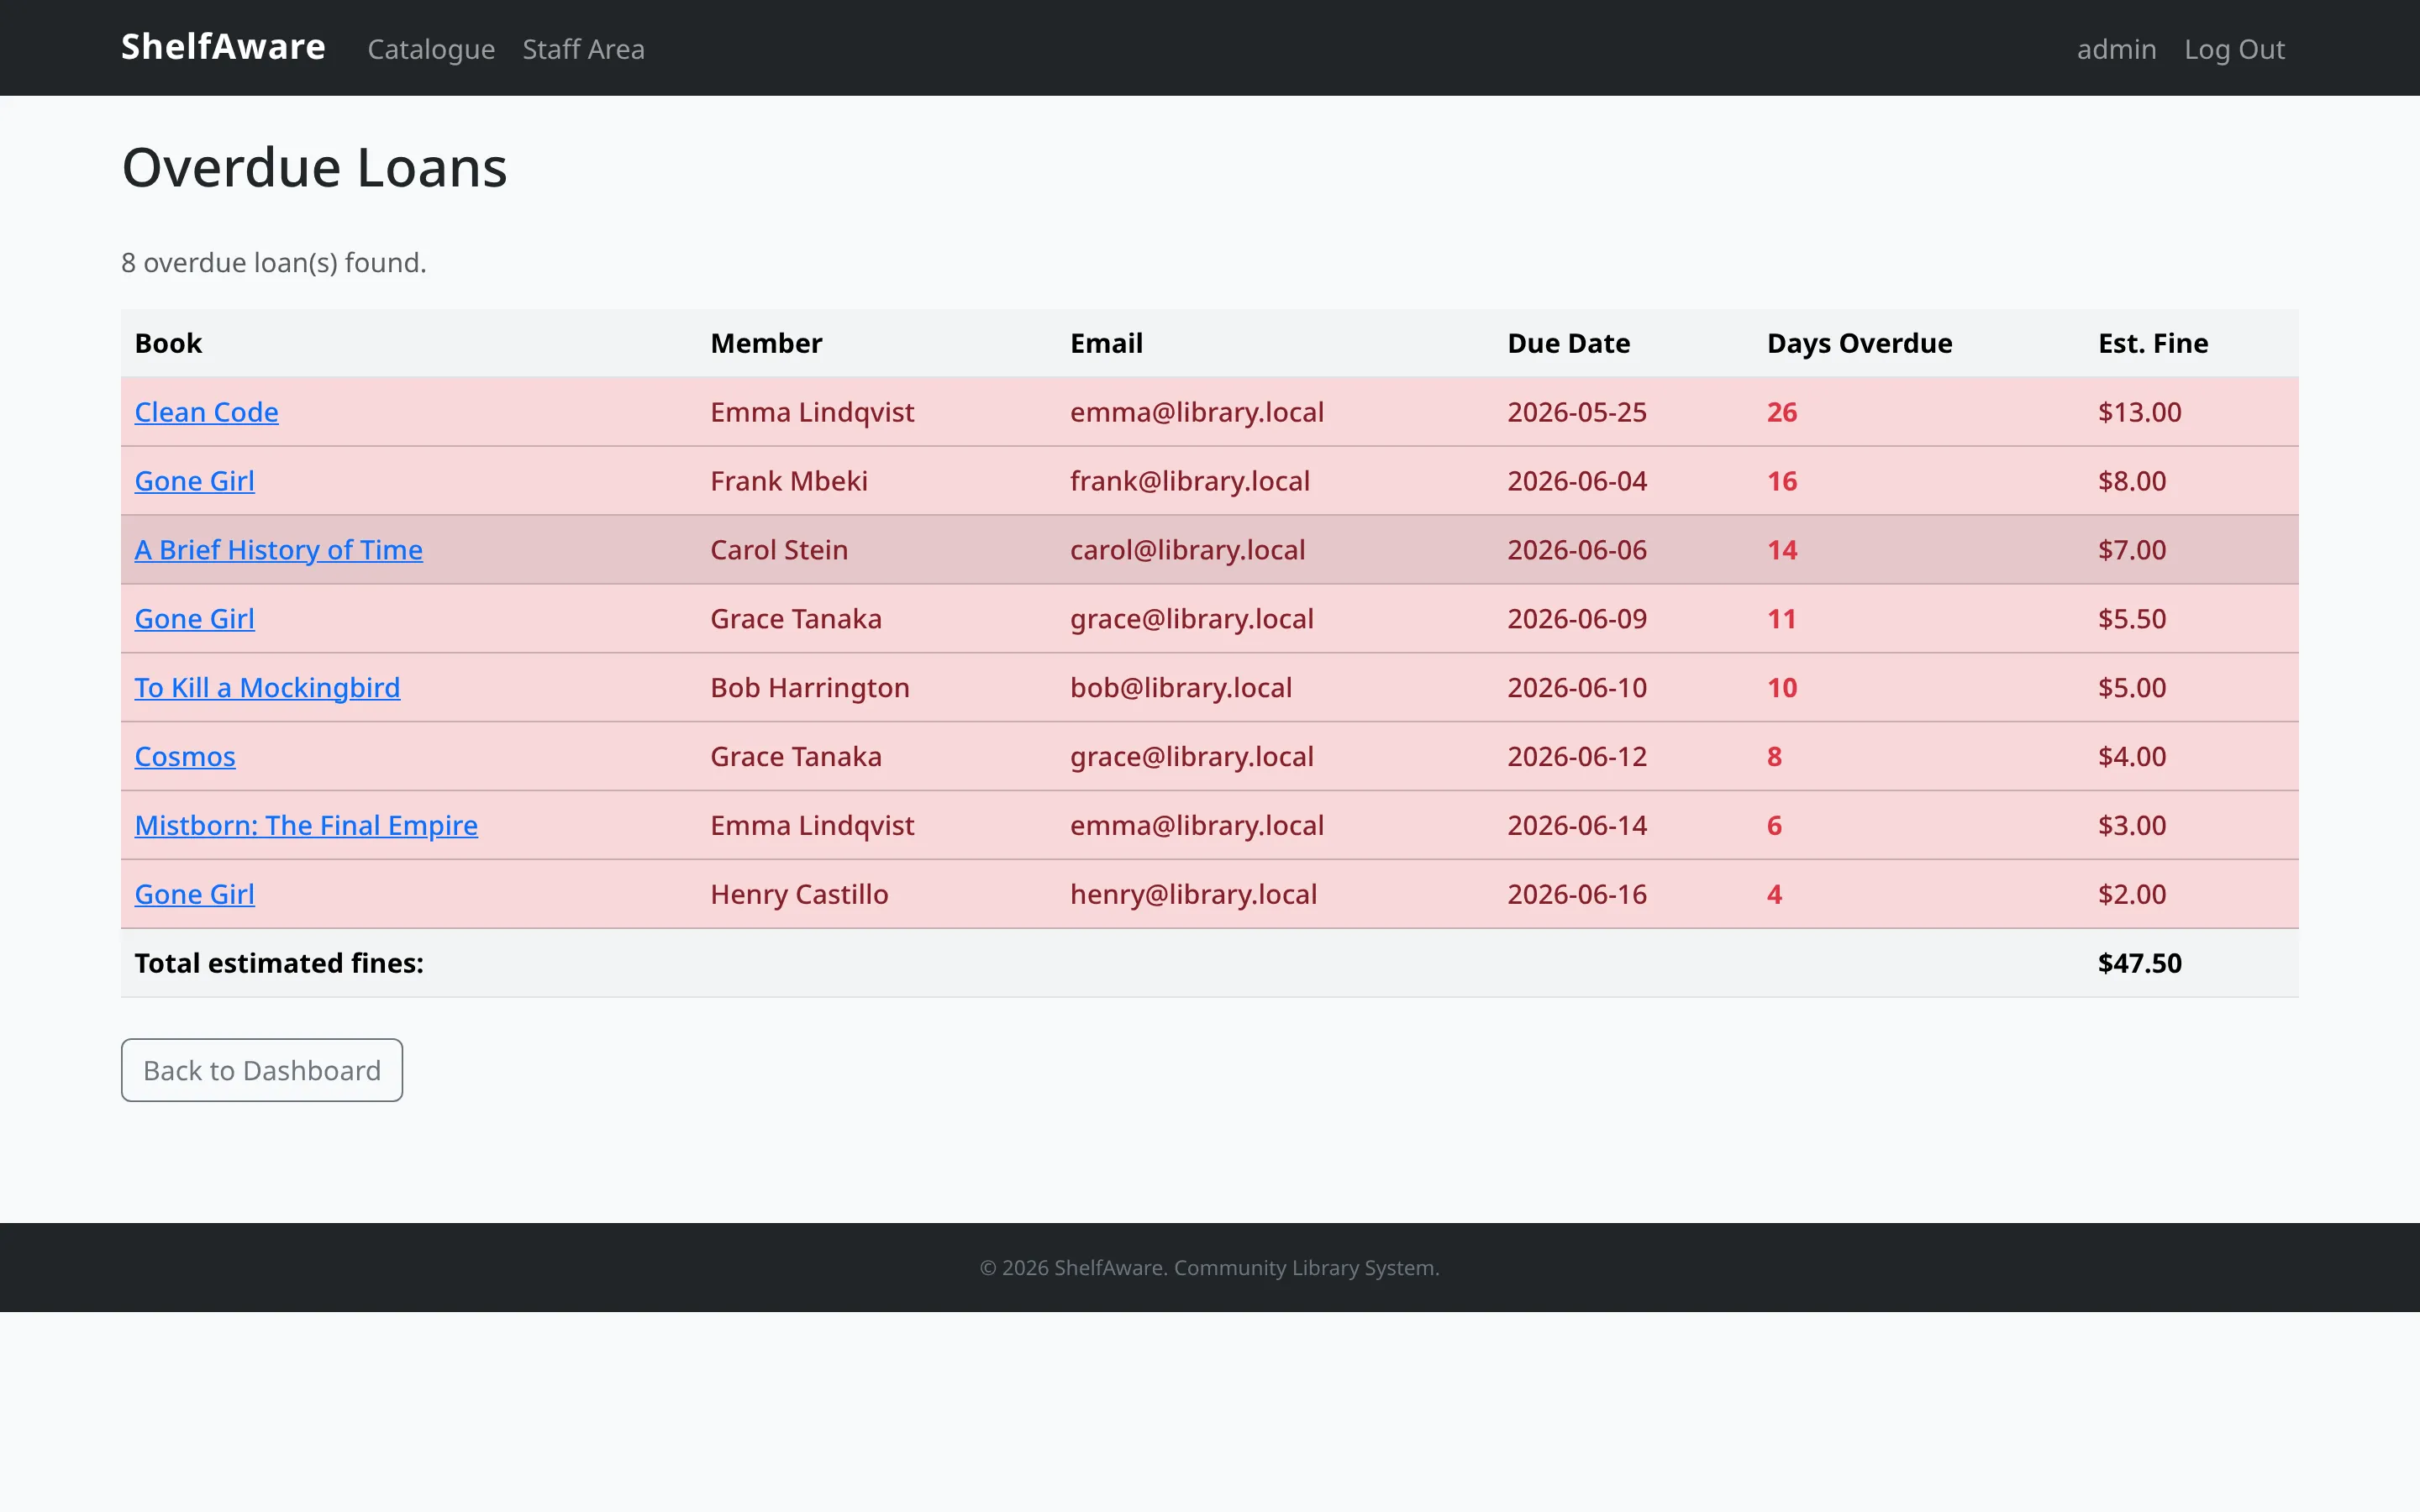
ShelfAware handles members, a catalogue, loans, a holds queue, overdue fines, and reviews. The return flow is the most interesting piece. It checks whether a book is overdue, computes the fine (daily rate × days late), inserts the fine row, and updates copy counts, all inside a single transaction. The holds queue auto-advances the moment a copy comes back. Four coordinated writes that must either all land or all roll back.
RepBase
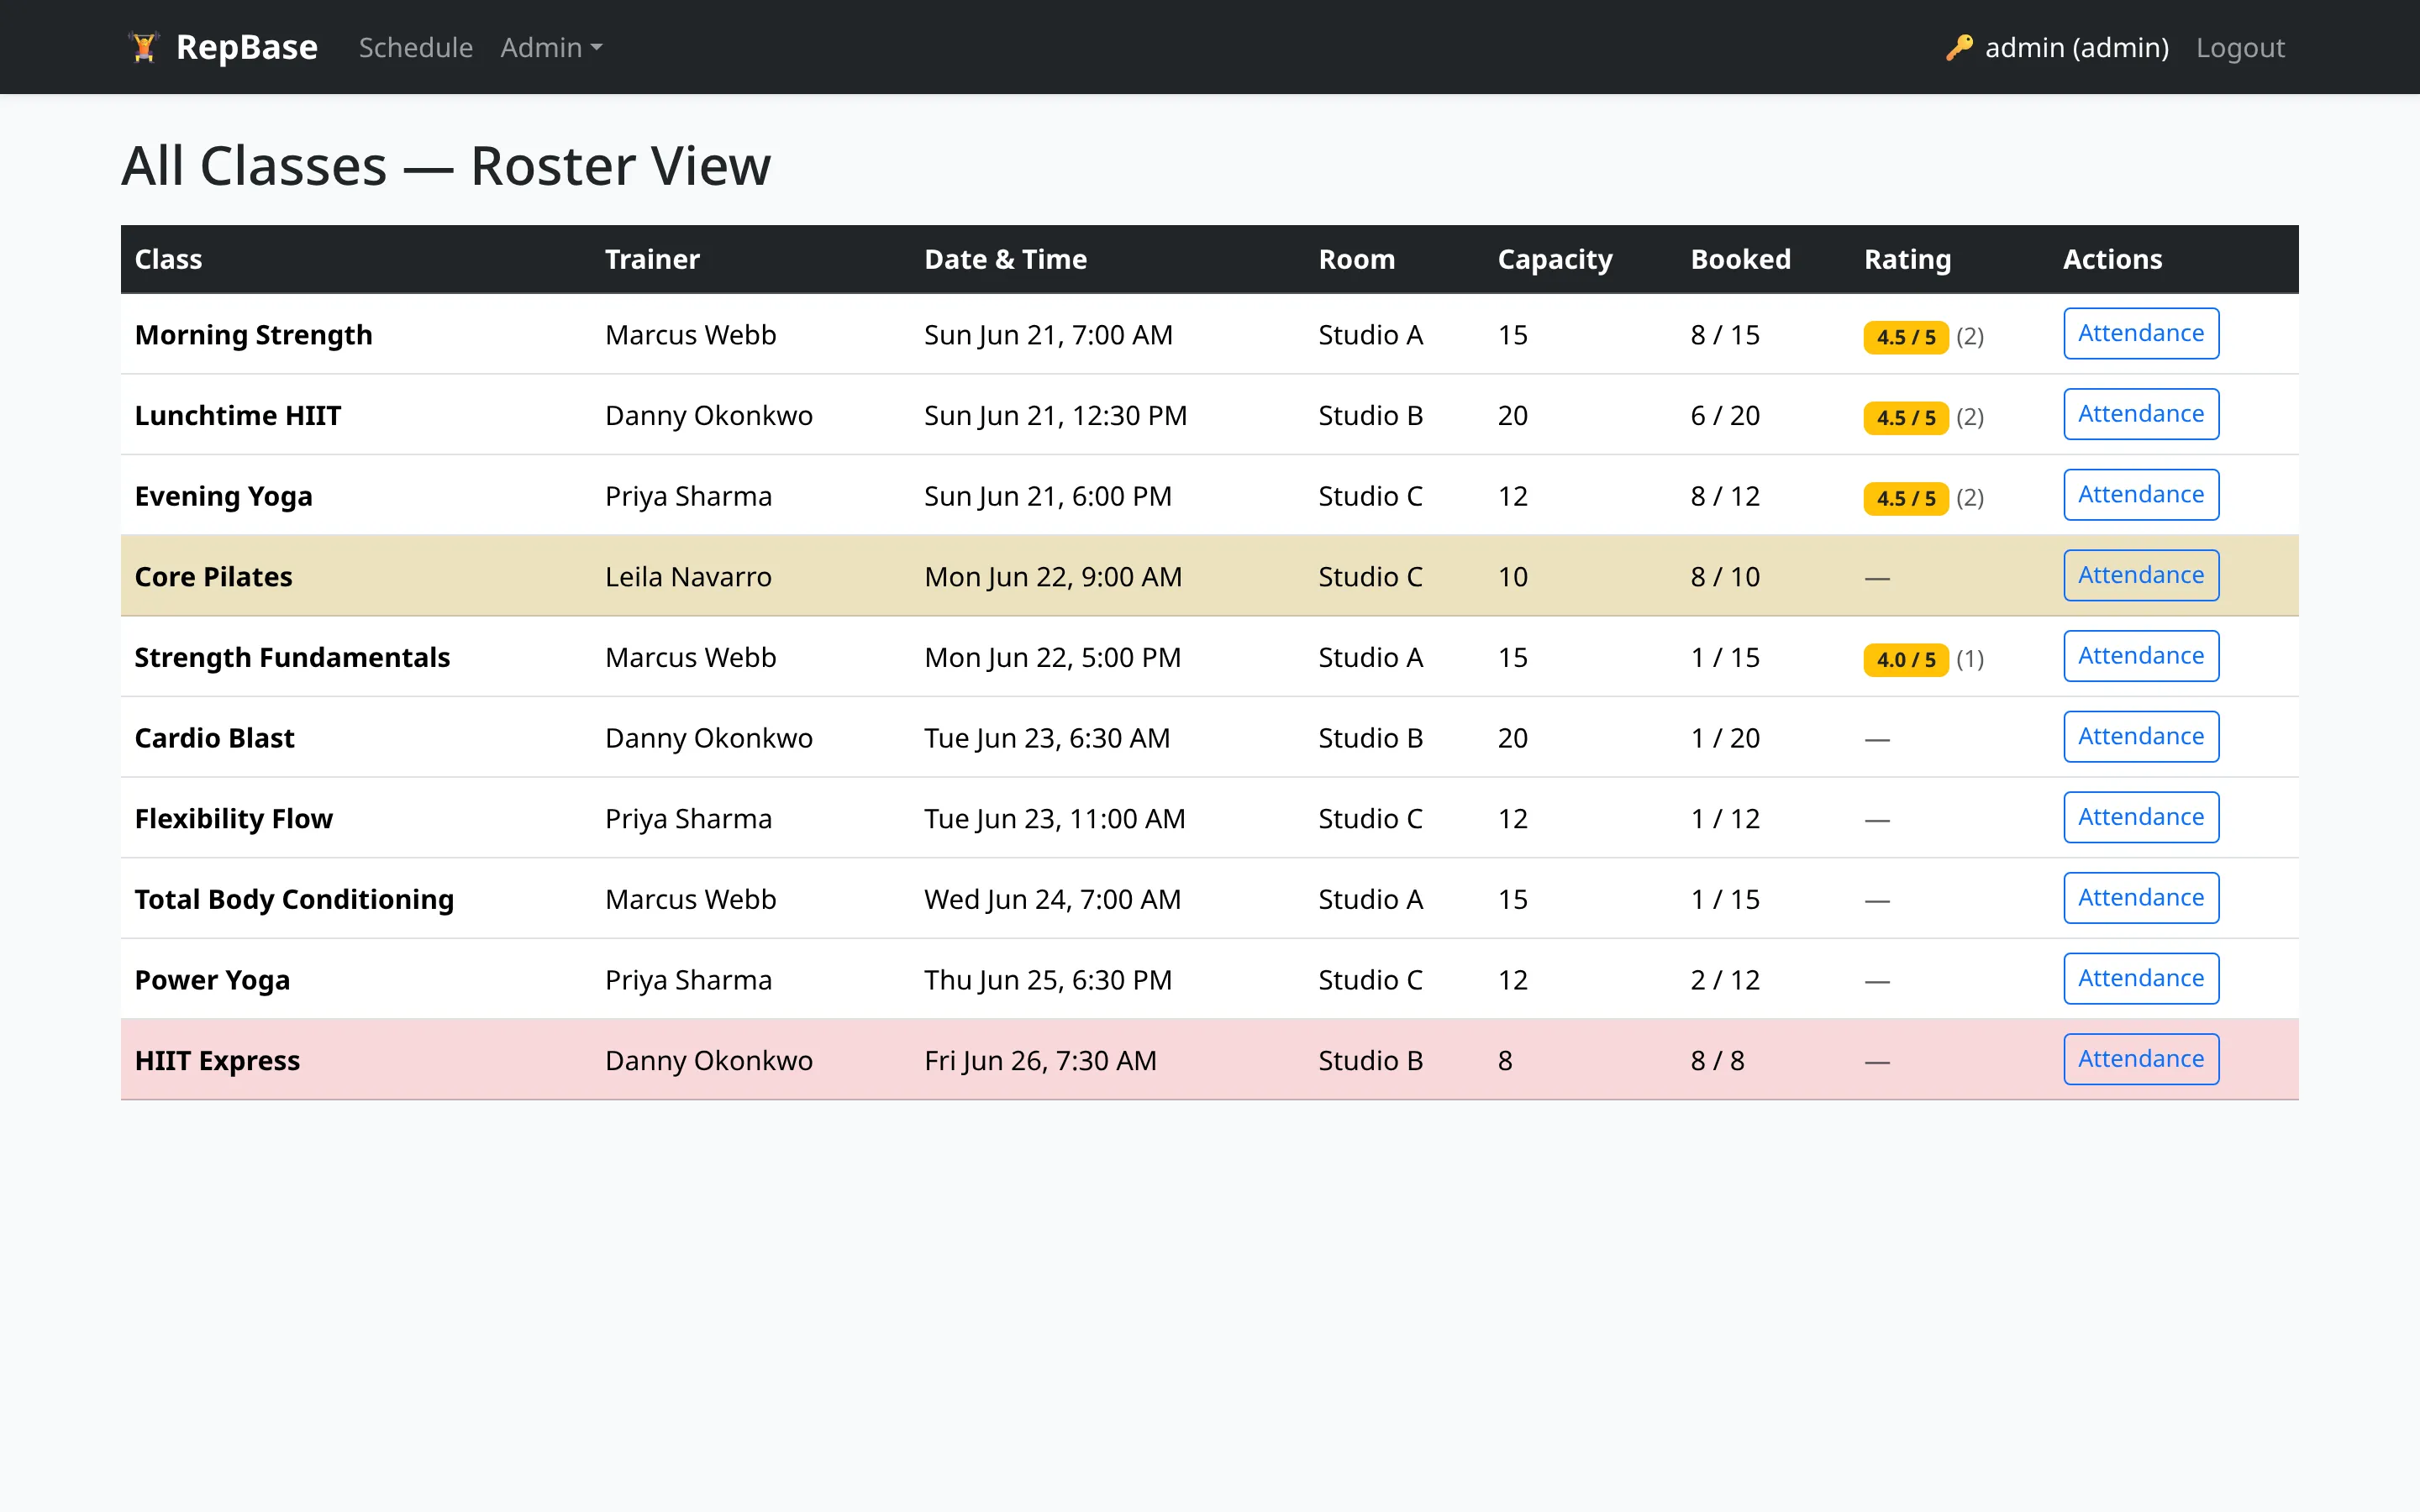
RepBase manages members, class bookings, waitlists,
attendance, and payments across member/trainer/admin roles. The booking flow is the transaction-
heavy one: booking a full class drops you onto the waitlist, and cancelling a spot
auto-promotes the next person in line. The “seats left” figure is a LEFT JOIN aggregate
against active bookings, not a counter you can let drift:
SELECT c.Title, c.Capacity - COUNT(b.Booking_id) AS seats_leftFROM class cLEFT JOIN booking b ON b.Class_id = c.Class_id AND b.Status = 'booked'GROUP BY c.Class_id;Under a 50-concurrent-user load test (Docker Compose, table seeded with 8,000 booking rows), the seats-left query completed in an average of 3.2ms. A PHP loop doing the same calculation row-by-row — fetching all bookings and summing in application code — averaged 47ms on the same dataset, roughly fifteen times slower. At 200 concurrent users the SQL aggregate held at 4.1ms while the PHP loop climbed past 200ms. The difference is not the query versus the loop in isolation; it’s that the aggregate runs inside the database engine, which keeps the booking rows in a buffer pool and never sends them across the PHP/MySQL boundary at all.
Takeaways
Building these without a framework forced me to handle the things an ORM normally papers over: where a transaction begins and commits, what happens to a concurrent booking when capacity is already full, and how to keep derived numbers (stock, seats, fines) honest by deriving them from the source rows instead of caching a count that can drift. Each ships with a Docker Compose setup that seeds the database on first boot, so any of them is one command away from running.